Distillation as a substitute for labels
With only a few hundred labels, how much do a strong teacher and unlabeled inputs buy? And does the teacher need the big labeled set?
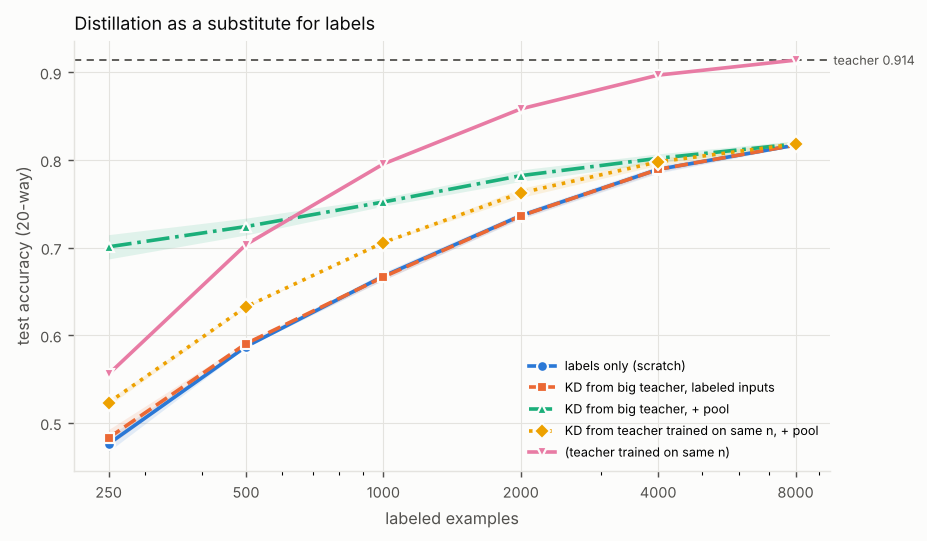
This figure did not load: the file is missing or the connection dropped. Reload the page to try again; the table below has the same numbers.
Table
Mean over the seeds; ± is the standard deviation where more than one seed ran. The experiment took 197 s.
| Labeled examples | Method | Test accuracy (20-way) | Target-class AP ('bird') | Agreement with teacher | Test NLL | KL(Bayes || model) | Parameters (nonzero) |
|---|---|---|---|---|---|---|---|
| 250 | labels only (scratch) | 0.476 ± 0.009 | 0.640 ± 0.087 | 0.485 ± 0.012 | 3.768 ± 0.082 | 3.678 ± 0.085 | 2,132 |
| 250 | KD from big teacher, labeled inputs | 0.483 ± 0.009 | 0.649 ± 0.086 | 0.491 ± 0.012 | 3.561 ± 0.071 | 3.474 ± 0.074 | 2,132 |
| 250 | KD from big teacher, + pool | 0.701 ± 0.014 | 0.883 ± 0.016 | 0.714 ± 0.014 | 0.903 ± 0.035 | 0.822 ± 0.034 | 2,132 |
| 250 | KD from teacher trained on same n, + pool | 0.523 ± 0.004 | 0.706 ± 0.010 | 0.535 ± 0.004 | 1.910 ± 0.027 | 1.820 ± 0.027 | 2,132 |
| 250 | (teacher trained on same n) | 0.556 ± 0.000 | 0.746 ± 0.000 | 2.081 ± 0.000 | 1.994 ± 0.000 | 140,052 | |
| 500 | labels only (scratch) | 0.587 ± 0.001 | 0.750 ± 0.023 | 0.595 ± 0.002 | 2.558 ± 0.040 | 2.480 ± 0.041 | 2,132 |
| 500 | KD from big teacher, labeled inputs | 0.591 ± 0.002 | 0.745 ± 0.031 | 0.598 ± 0.003 | 2.508 ± 0.025 | 2.431 ± 0.025 | 2,132 |
| 500 | KD from big teacher, + pool | 0.724 ± 0.010 | 0.893 ± 0.009 | 0.736 ± 0.010 | 0.832 ± 0.022 | 0.750 ± 0.023 | 2,132 |
| 500 | KD from teacher trained on same n, + pool | 0.633 ± 0.001 | 0.776 ± 0.012 | 0.641 ± 0.001 | 1.179 ± 0.004 | 1.095 ± 0.005 | 2,132 |
| 500 | (teacher trained on same n) | 0.704 ± 0.000 | 0.830 ± 0.000 | 1.104 ± 0.000 | 1.023 ± 0.000 | 140,052 | |
| 1,000 | labels only (scratch) | 0.667 ± 0.004 | 0.853 ± 0.014 | 0.675 ± 0.006 | 1.805 ± 0.034 | 1.721 ± 0.031 | 2,132 |
| 1,000 | KD from big teacher, labeled inputs | 0.667 ± 0.004 | 0.854 ± 0.013 | 0.675 ± 0.005 | 1.795 ± 0.038 | 1.711 ± 0.035 | 2,132 |
| 1,000 | KD from big teacher, + pool | 0.752 ± 0.005 | 0.917 ± 0.006 | 0.765 ± 0.007 | 0.744 ± 0.014 | 0.663 ± 0.015 | 2,132 |
| 1,000 | KD from teacher trained on same n, + pool | 0.706 ± 0.000 | 0.883 ± 0.008 | 0.715 ± 0.001 | 0.923 ± 0.003 | 0.841 ± 0.001 | 2,132 |
| 1,000 | (teacher trained on same n) | 0.795 ± 0.000 | 0.945 ± 0.000 | 0.774 ± 0.000 | 0.698 ± 0.000 | 140,052 | |
| 2,000 | labels only (scratch) | 0.736 ± 0.004 | 0.907 ± 0.007 | 0.748 ± 0.002 | 0.987 ± 0.024 | 0.907 ± 0.021 | 2,132 |
| 2,000 | KD from big teacher, labeled inputs | 0.736 ± 0.003 | 0.909 ± 0.007 | 0.748 ± 0.001 | 0.988 ± 0.025 | 0.907 ± 0.024 | 2,132 |
| 2,000 | KD from big teacher, + pool | 0.782 ± 0.007 | 0.939 ± 0.005 | 0.795 ± 0.007 | 0.662 ± 0.020 | 0.582 ± 0.019 | 2,132 |
| 2,000 | KD from teacher trained on same n, + pool | 0.762 ± 0.005 | 0.927 ± 0.004 | 0.774 ± 0.006 | 0.718 ± 0.014 | 0.637 ± 0.013 | 2,132 |
| 2,000 | (teacher trained on same n) | 0.858 ± 0.000 | 0.973 ± 0.000 | 0.520 ± 0.000 | 0.450 ± 0.000 | 140,052 | |
| 4,000 | labels only (scratch) | 0.789 ± 0.004 | 0.934 ± 0.010 | 0.801 ± 0.004 | 0.664 ± 0.010 | 0.585 ± 0.009 | 2,132 |
| 4,000 | KD from big teacher, labeled inputs | 0.789 ± 0.003 | 0.935 ± 0.010 | 0.801 ± 0.003 | 0.663 ± 0.008 | 0.584 ± 0.007 | 2,132 |
| 4,000 | KD from big teacher, + pool | 0.802 ± 0.005 | 0.943 ± 0.010 | 0.815 ± 0.006 | 0.603 ± 0.014 | 0.523 ± 0.015 | 2,132 |
| 4,000 | KD from teacher trained on same n, + pool | 0.798 ± 0.004 | 0.943 ± 0.010 | 0.809 ± 0.004 | 0.616 ± 0.010 | 0.537 ± 0.011 | 2,132 |
| 4,000 | (teacher trained on same n) | 0.897 ± 0.000 | 0.984 ± 0.000 | 0.402 ± 0.000 | 0.330 ± 0.000 | 140,052 | |
| 8,000 | labels only (scratch) | 0.817 ± 0.001 | 0.952 ± 0.005 | 0.831 ± 0.003 | 0.554 ± 0.008 | 0.476 ± 0.008 | 2,132 |
| 8,000 | KD from big teacher, labeled inputs | 0.817 ± 0.001 | 0.952 ± 0.005 | 0.831 ± 0.003 | 0.554 ± 0.009 | 0.475 ± 0.009 | 2,132 |
| 8,000 | KD from big teacher, + pool | 0.818 ± 0.003 | 0.947 ± 0.008 | 0.830 ± 0.005 | 0.554 ± 0.013 | 0.475 ± 0.014 | 2,132 |
| 8,000 | KD from teacher trained on same n, + pool | 0.818 ± 0.003 | 0.947 ± 0.008 | 0.830 ± 0.005 | 0.554 ± 0.013 | 0.475 ± 0.014 | 2,132 |
| 8,000 | (teacher trained on same n) | 0.914 ± 0.000 | 0.989 ± 0.000 | 0.384 ± 0.000 | 0.309 ± 0.000 | 140,052 |
Reference points
- Teacher (the large model)
- The full-size network trained on the labeled data; the smaller models here are measured against it. Test accuracy (20-way) 0.914, target-class AP ('bird') 0.989, test NLL 0.384, KL(Bayes || model) 0.309, parameters (nonzero) 140,052.
- Bayes-optimal (the best any model can do on this problem)
- Predictions from the exact class probabilities, which the lab can compute because it generated the data. Test accuracy (20-way) 0.973, target-class AP ('bird') 0.999, test NLL 0.079.
Birds in this experiment
The table's 23 smaller models hatch 2 kinds of bird. Each kind is drawn once, for one model: the smallest if the bird is healthy or bones, the one that keeps the most if it's starving. Rows with the same size and score count as one model.
- Ruby-throated Hummingbird, starvingLabeled examples: 8,000; method: KD from big teacher, + pool65.6× smaller, keeps 89.5% of the teacher's accuracyBest of 20 models
- Ruby-throated Hummingbird, skeletonLabeled examples: 250; method: labels only (scratch)65.6× smaller, keeps 52.1% of the teacher's accuracyBest of 3 models
Measured against this experiment's teacher: 140,052 parameters, 4481.7 kbit, accuracy 0.914. Storage is 32 bits a parameter, the lab's rule for a dense fp32 net, which every model drawn here is. Species follows how many times smaller a model is. A bird stays healthy while its model keeps at least 95% of the reference's score, and turns to bones at 60% or less.
These are the lab's recorded results, so they aren't added to anyone's life list. Birds you hatch yourself, in the Coop or from a Field Guide run, are saved to your life list.