Lottery tickets: is the mask or the init the secret?
Iterative magnitude pruning, then retrain the sparse net from (a) its original init, (b) an early-training rewind point, (c) a fresh random init, (d) its trained weights. Plus a random mask control.
Methods: Lottery tickets
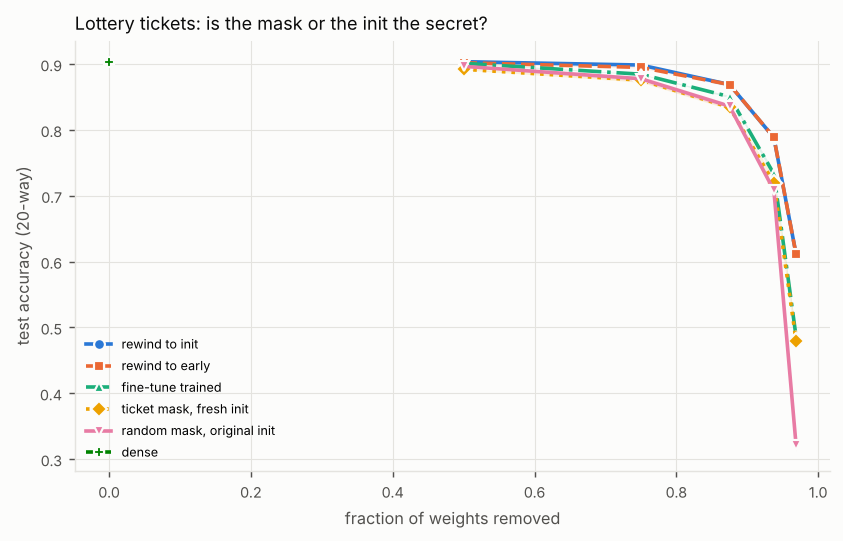
This figure did not load: the file is missing or the connection dropped. Reload the page to try again; the table below has the same numbers.
Table
Mean over the seeds; ± is the standard deviation where more than one seed ran. The experiment took 167 s.
| Fraction of weights removed | Method | Test accuracy (20-way) | Target-class AP ('bird') | Test NLL | KL(Bayes || model) | Parameters (nonzero) |
|---|---|---|---|---|---|---|
| 0.500 | rewind to init | 0.904 ± 0.000 | 0.988 ± 0.001 | 0.341 ± 0.010 | 0.270 ± 0.012 | 10,516 |
| 0.500 | rewind to early | 0.902 ± 0.001 | 0.988 ± 0.002 | 0.355 ± 0.010 | 0.284 ± 0.014 | 10,516 |
| 0.500 | fine-tune trained | 0.901 ± 0.001 | 0.987 ± 0.001 | 0.440 ± 0.012 | 0.374 ± 0.016 | 10,516 |
| 0.500 | ticket mask, fresh init | 0.892 ± 0.001 | 0.987 ± 0.001 | 0.329 ± 0.008 | 0.254 ± 0.004 | 10,516 |
| 0.500 | random mask, original init | 0.897 ± 0.002 | 0.984 ± 0.004 | 0.328 ± 0.005 | 0.253 ± 0.005 | 10,592.5 ± 60.5 |
| 0.750 | rewind to init | 0.899 ± 0.001 | 0.985 ± 0.001 | 0.339 ± 0.006 | 0.267 ± 0.005 | 5,396 |
| 0.750 | rewind to early | 0.895 ± 0.001 | 0.984 ± 0.003 | 0.352 ± 0.001 | 0.279 ± 0.003 | 5,396 |
| 0.750 | fine-tune trained | 0.885 ± 0.000 | 0.980 ± 0.002 | 0.461 ± 0.012 | 0.387 ± 0.010 | 5,396 |
| 0.750 | ticket mask, fresh init | 0.876 ± 0.003 | 0.978 ± 0.002 | 0.377 ± 0.002 | 0.298 ± 0.002 | 5,396 |
| 0.750 | random mask, original init | 0.878 ± 0.004 | 0.974 ± 0.001 | 0.370 ± 0.010 | 0.298 ± 0.008 | 5,319 ± 58 |
| 0.875 | rewind to init | 0.869 ± 0.004 | 0.971 ± 0.002 | 0.407 ± 0.008 | 0.331 ± 0.008 | 2,836 |
| 0.875 | rewind to early | 0.869 ± 0.001 | 0.976 ± 0.002 | 0.407 ± 0.005 | 0.326 ± 0.003 | 2,836 |
| 0.875 | fine-tune trained | 0.851 ± 0.002 | 0.965 ± 0.001 | 0.494 ± 0.005 | 0.418 ± 0.009 | 2,836 |
| 0.875 | ticket mask, fresh init | 0.834 ± 0.003 | 0.956 ± 0.010 | 0.497 ± 0.000 | 0.416 ± 0.002 | 2,836 |
| 0.875 | random mask, original init | 0.836 ± 0.004 | 0.966 ± 0.003 | 0.491 ± 0.013 | 0.410 ± 0.014 | 2,866 ± 41 |
| 0.938 | rewind to init | 0.788 ± 0.000 | 0.940 ± 0.015 | 0.635 ± 0.001 | 0.556 ± 0.002 | 1,556 |
| 0.938 | rewind to early | 0.789 ± 0.005 | 0.944 ± 0.011 | 0.631 ± 0.015 | 0.552 ± 0.014 | 1,556 |
| 0.938 | fine-tune trained | 0.733 ± 0.004 | 0.877 ± 0.024 | 0.815 ± 0.013 | 0.733 ± 0.013 | 1,556 |
| 0.938 | ticket mask, fresh init | 0.720 ± 0.009 | 0.898 ± 0.015 | 0.836 ± 0.029 | 0.752 ± 0.028 | 1,556 |
| 0.938 | random mask, original init | 0.708 ± 0.006 | 0.885 ± 0.029 | 0.889 ± 0.019 | 0.808 ± 0.019 | 1,551 ± 14 |
| 0.969 | rewind to init | 0.612 ± 0.002 | 0.886 ± 0.024 | 1.152 ± 0.001 | 1.070 ± 0.004 | 916 |
| 0.969 | rewind to early | 0.611 ± 0.001 | 0.852 ± 0.025 | 1.161 ± 0.001 | 1.076 ± 0.005 | 916 |
| 0.969 | fine-tune trained | 0.487 ± 0.003 | 0.756 ± 0.091 | 1.541 ± 0.001 | 1.457 ± 0.001 | 916 |
| 0.969 | ticket mask, fresh init | 0.480 ± 0.013 | 0.686 ± 0.091 | 1.580 ± 0.043 | 1.495 ± 0.044 | 916 |
| 0.969 | random mask, original init | 0.322 ± 0.010 | 0.454 ± 0.042 | 2.090 ± 0.002 | 2.009 ± 0.002 | 914 ± 16 |
| 0 | dense | 0.904 ± 0.002 | 0.988 ± 0.001 | 0.328 ± 0.010 | 0.256 ± 0.012 | 20,756 |
Reference points
- Bayes-optimal (the best any model can do on this problem)
- Predictions from the exact class probabilities, which the lab can compute because it generated the data. Test accuracy (20-way) 0.973, target-class AP ('bird') 0.999, test NLL 0.079.