Born-again networks (self-distillation)
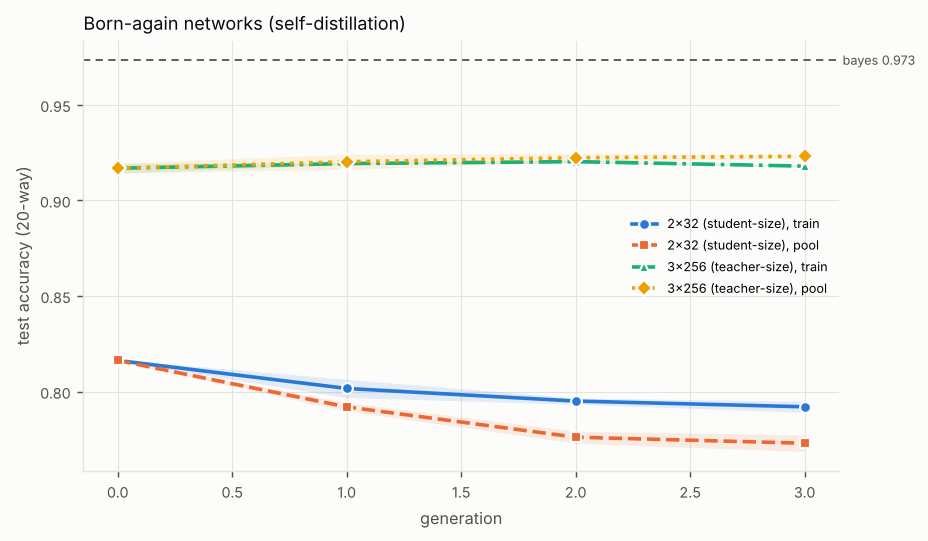
Can a model teach a copy of itself to be better? Repeat for several generations, small and big.
This figure did not load: the file is missing or the connection dropped. Reload the page to try again; the table below has the same numbers.
Table
Mean over the seeds; ± is the standard deviation where more than one seed ran. The experiment took 262 s.
| Arch | Transfer | Generation | Test accuracy (20-way) | Target-class AP ('bird') | Agreement with teacher | Test NLL | KL(Bayes || model) | Parameters (nonzero) |
|---|---|---|---|---|---|---|---|---|
| 2x32 (student-size) | train | 0 | 0.816 ± 0.001 | 0.949 ± 0.001 | 0.555 ± 0.009 | 0.478 ± 0.009 | 2,132 | |
| 2x32 (student-size) | train | 1 | 0.802 ± 0.005 | 0.937 ± 0.007 | 0.819 ± 0.003 | 0.595 ± 0.011 | 0.514 ± 0.009 | 2,132 |
| 2x32 (student-size) | train | 2 | 0.795 ± 0.002 | 0.938 ± 0.001 | 0.838 ± 0.003 | 0.619 ± 0.010 | 0.538 ± 0.008 | 2,132 |
| 2x32 (student-size) | train | 3 | 0.792 ± 0.003 | 0.939 ± 0.005 | 0.848 ± 0.003 | 0.628 ± 0.001 | 0.547 ± 0.001 | 2,132 |
| 2x32 (student-size) | pool | 0 | 0.816 ± 0.001 | 0.949 ± 0.001 | 0.555 ± 0.009 | 0.478 ± 0.009 | 2,132 | |
| 2x32 (student-size) | pool | 1 | 0.792 ± 0.002 | 0.932 ± 0.000 | 0.818 ± 0.000 | 0.620 ± 0.003 | 0.539 ± 0.002 | 2,132 |
| 2x32 (student-size) | pool | 2 | 0.776 ± 0.003 | 0.921 ± 0.005 | 0.829 ± 0.003 | 0.672 ± 0.012 | 0.589 ± 0.010 | 2,132 |
| 2x32 (student-size) | pool | 3 | 0.773 ± 0.004 | 0.922 ± 0.005 | 0.841 ± 0.005 | 0.687 ± 0.001 | 0.605 ± 0.002 | 2,132 |
| 3x256 (teacher-size) | train | 0 | 0.917 ± 0.003 | 0.989 ± 0.001 | 0.373 ± 0.016 | 0.302 ± 0.013 | 140,052 | |
| 3x256 (teacher-size) | train | 1 | 0.919 ± 0.001 | 0.991 ± 0.001 | 0.950 ± 0.002 | 0.367 ± 0.000 | 0.297 ± 0.001 | 140,052 |
| 3x256 (teacher-size) | train | 2 | 0.920 ± 0.001 | 0.990 ± 0.001 | 0.953 ± 0.000 | 0.364 ± 0.001 | 0.297 ± 0.000 | 140,052 |
| 3x256 (teacher-size) | train | 3 | 0.918 ± 0.000 | 0.988 ± 0.000 | 0.955 ± 0.002 | 0.370 ± 0.000 | 0.299 ± 0.001 | 140,052 |
| 3x256 (teacher-size) | pool | 0 | 0.917 ± 0.003 | 0.989 ± 0.001 | 0.373 ± 0.016 | 0.302 ± 0.013 | 140,052 | |
| 3x256 (teacher-size) | pool | 1 | 0.920 ± 0.004 | 0.990 ± 0.001 | 0.960 ± 0.001 | 0.340 ± 0.015 | 0.267 ± 0.013 | 140,052 |
| 3x256 (teacher-size) | pool | 2 | 0.922 ± 0.002 | 0.990 ± 0.001 | 0.967 ± 0.001 | 0.325 ± 0.011 | 0.250 ± 0.008 | 140,052 |
| 3x256 (teacher-size) | pool | 3 | 0.923 ± 0.001 | 0.990 ± 0.000 | 0.965 ± 0.000 | 0.318 ± 0.007 | 0.245 ± 0.007 | 140,052 |
Reference points
- Bayes-optimal (the best any model can do on this problem)
- Predictions from the exact class probabilities, which the lab can compute because it generated the data. Test accuracy (20-way) 0.973, target-class AP ('bird') 0.999, test NLL 0.079.