How small can a one-class specialist be?
Target-class AP vs. size for a 20-way generalist student and for specialists whose heads keep less and less of the teacher's label space.
Methods: Specialist heads
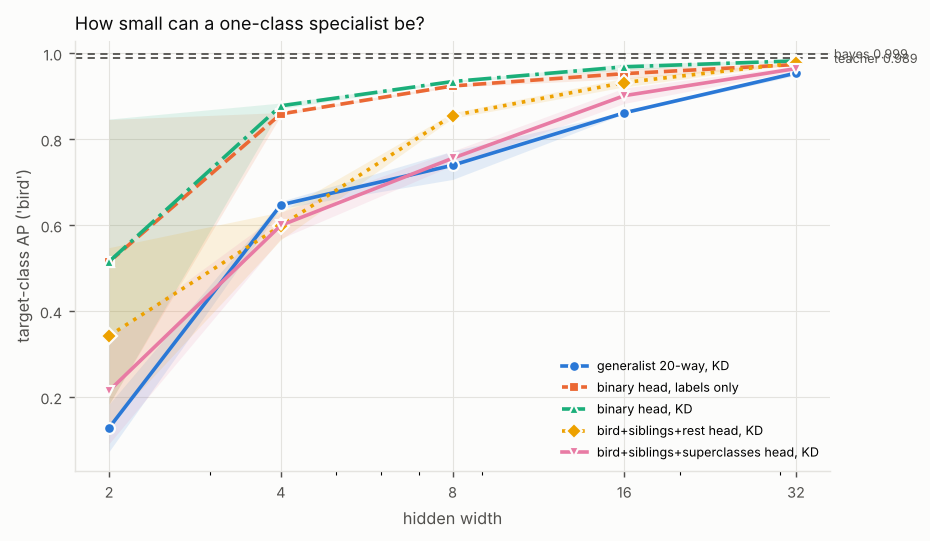
This figure did not load: the file is missing or the connection dropped. Reload the page to try again; the table below has the same numbers.
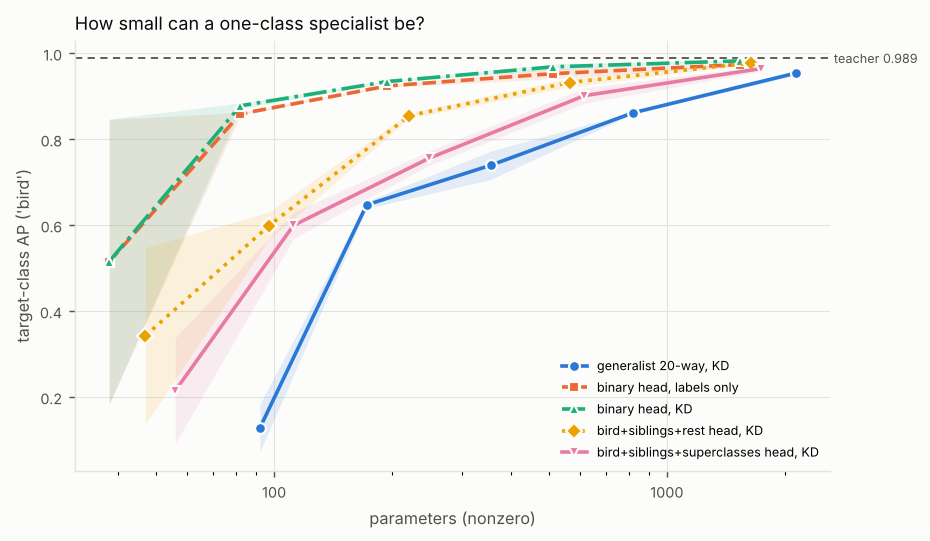
This figure did not load: the file is missing or the connection dropped. Reload the page to try again; the table below has the same numbers.
Table
Mean over the seeds; ± is the standard deviation where more than one seed ran. The experiment took 83 s.
| Hidden width | Method | Test accuracy (20-way) | Target-class AP ('bird') | Test NLL | KL(Bayes || model) | Parameters (nonzero) |
|---|---|---|---|---|---|---|
| 2 | generalist 20-way, KD | 0.123 ± 0.050 | 0.129 ± 0.055 | 2.739 ± 0.182 | 2.654 ± 0.182 | 92 |
| 2 | binary head, labels only | 0.515 ± 0.331 | 38 | |||
| 2 | binary head, KD | 0.516 ± 0.332 | 38 | |||
| 2 | bird+siblings+rest head, KD | 0.343 ± 0.205 | 47 | |||
| 2 | bird+siblings+superclasses head, KD | 0.215 ± 0.123 | 56 | |||
| 4 | generalist 20-way, KD | 0.324 ± 0.012 | 0.648 ± 0.008 | 1.989 ± 0.040 | 1.904 ± 0.040 | 172 |
| 4 | binary head, labels only | 0.859 ± 0.003 | 82 | |||
| 4 | binary head, KD | 0.878 ± 0.007 | 82 | |||
| 4 | bird+siblings+rest head, KD | 0.599 ± 0.032 | 97 | |||
| 4 | bird+siblings+superclasses head, KD | 0.600 ± 0.031 | 112 | |||
| 8 | generalist 20-way, KD | 0.456 ± 0.015 | 0.740 ± 0.033 | 1.603 ± 0.028 | 1.519 ± 0.029 | 356 |
| 8 | binary head, labels only | 0.924 ± 0.003 | 194 | |||
| 8 | binary head, KD | 0.935 ± 0.002 | 194 | |||
| 8 | bird+siblings+rest head, KD | 0.855 ± 0.006 | 221 | |||
| 8 | bird+siblings+superclasses head, KD | 0.756 ± 0.017 | 248 | |||
| 16 | generalist 20-way, KD | 0.671 ± 0.008 | 0.862 ± 0.002 | 0.991 ± 0.023 | 0.909 ± 0.023 | 820 |
| 16 | binary head, labels only | 0.953 ± 0.012 | 514 | |||
| 16 | binary head, KD | 0.969 ± 0.007 | 514 | |||
| 16 | bird+siblings+rest head, KD | 0.932 ± 0.010 | 565 | |||
| 16 | bird+siblings+superclasses head, KD | 0.902 ± 0.018 | 616 | |||
| 32 | generalist 20-way, KD | 0.832 ± 0.005 | 0.954 ± 0.005 | 0.511 ± 0.013 | 0.433 ± 0.015 | 2,132 |
| 32 | binary head, labels only | 0.974 ± 0.003 | 1,538 | |||
| 32 | binary head, KD | 0.983 ± 0.002 | 1,538 | |||
| 32 | bird+siblings+rest head, KD | 0.978 ± 0.002 | 1,637 | |||
| 32 | bird+siblings+superclasses head, KD | 0.965 ± 0.006 | 1,736 |
Reference points
- Teacher (the large model)
- The full-size network trained on the labeled data; the smaller models here are measured against it. Test accuracy (20-way) 0.914, target-class AP ('bird') 0.989, test NLL 0.384, KL(Bayes || model) 0.309, parameters (nonzero) 140,052.
- Bayes-optimal (the best any model can do on this problem)
- Predictions from the exact class probabilities, which the lab can compute because it generated the data. Test accuracy (20-way) 0.973, target-class AP ('bird') 0.999, test NLL 0.079.
Birds in this experiment
The table's 25 smaller models hatch 3 kinds of bird. Each kind is drawn once, for one model: the smallest if the bird is healthy or bones, the one that keeps the most if it's starving.
- Ruby-throated Hummingbird, healthyHidden width: 16; method: binary head, labels only272.4× smaller, keeps 96.4% of the teacher's target-class APBest of 7 models
- Ruby-throated Hummingbird, starvingHidden width: 8; method: binary head, KD721.9× smaller, keeps 94.5% of the teacher's target-class APBest of 13 models
- Ruby-throated Hummingbird, skeletonHidden width: 2; method: binary head, labels only3685.5× smaller, keeps 52.1% of the teacher's target-class APBest of 5 models
Measured against this experiment's teacher: 140,052 parameters, 4481.7 kbit, target-class AP 0.989. Storage is 32 bits a parameter, the lab's rule for a dense fp32 net, which every model drawn here is. Species follows how many times smaller a model is. A bird stays healthy while its model keeps at least 95% of the reference's score, and turns to bones at 60% or less.
These are the lab's recorded results, so they aren't added to anyone's life list. Birds you hatch yourself, in the Coop or from a Field Guide run, are saved to your life list.