Train big, then compress
To end up with a 2xW network, is it better to train 2xW directly or to train something much wider and prune down to 2xW? (Li et al. 2020)
Methods: Train big, then prune to size
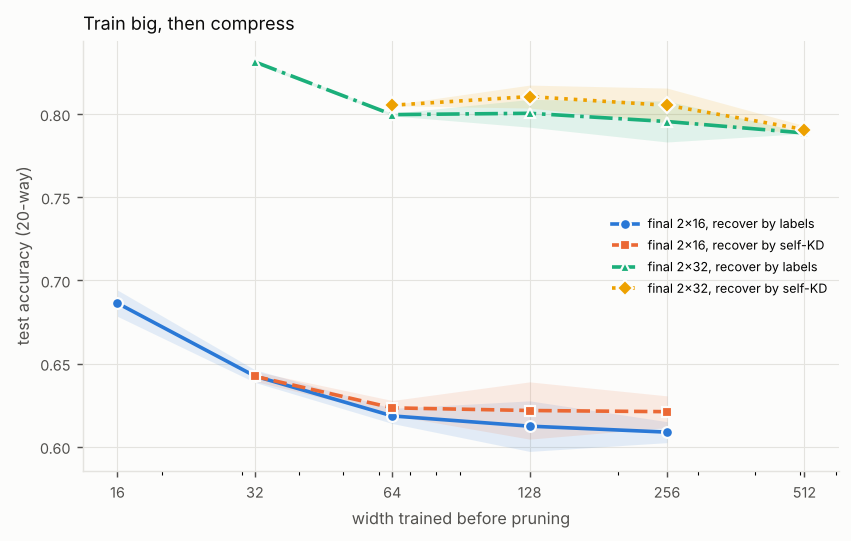
This figure did not load: the file is missing or the connection dropped. Reload the page to try again; the table below has the same numbers.
Table
Mean over the seeds; ± is the standard deviation where more than one seed ran. The experiment took 99 s.
| Target | Width trained before pruning | Method | Test accuracy (20-way) | Target-class AP ('bird') | Test NLL | KL(Bayes || model) | Parameters (nonzero) |
|---|---|---|---|---|---|---|---|
| final 2x16 | 16 | labels | 0.686 ± 0.008 | 0.854 ± 0.010 | 0.945 ± 0.015 | 0.862 ± 0.015 | 820 |
| final 2x16 | 32 | labels | 0.643 ± 0.004 | 0.860 ± 0.015 | 1.056 ± 0.025 | 0.973 ± 0.026 | 820 |
| final 2x16 | 32 | self-KD | 0.642 ± 0.003 | 0.857 ± 0.013 | 1.058 ± 0.020 | 0.975 ± 0.020 | 820 |
| final 2x16 | 64 | labels | 0.619 ± 0.005 | 0.823 ± 0.013 | 1.129 ± 0.018 | 1.047 ± 0.017 | 820 |
| final 2x16 | 64 | self-KD | 0.623 ± 0.004 | 0.835 ± 0.015 | 1.104 ± 0.017 | 1.022 ± 0.016 | 820 |
| final 2x16 | 128 | labels | 0.612 ± 0.015 | 0.806 ± 0.012 | 1.151 ± 0.037 | 1.069 ± 0.035 | 820 |
| final 2x16 | 128 | self-KD | 0.622 ± 0.017 | 0.813 ± 0.019 | 1.134 ± 0.044 | 1.052 ± 0.042 | 820 |
| final 2x16 | 256 | labels | 0.609 ± 0.006 | 0.827 ± 0.030 | 1.152 ± 0.023 | 1.069 ± 0.022 | 820 |
| final 2x16 | 256 | self-KD | 0.621 ± 0.010 | 0.837 ± 0.017 | 1.126 ± 0.019 | 1.044 ± 0.019 | 820 |
| final 2x32 | 32 | labels | 0.831 ± 0.001 | 0.958 ± 0.002 | 0.520 ± 0.005 | 0.443 ± 0.005 | 2,132 |
| final 2x32 | 64 | labels | 0.800 ± 0.001 | 0.943 ± 0.012 | 0.605 ± 0.000 | 0.524 ± 0.001 | 2,132 |
| final 2x32 | 64 | self-KD | 0.805 ± 0.000 | 0.947 ± 0.010 | 0.588 ± 0.001 | 0.508 ± 0.001 | 2,132 |
| final 2x32 | 128 | labels | 0.800 ± 0.008 | 0.938 ± 0.006 | 0.614 ± 0.018 | 0.537 ± 0.016 | 2,132 |
| final 2x32 | 128 | self-KD | 0.810 ± 0.007 | 0.945 ± 0.005 | 0.587 ± 0.016 | 0.510 ± 0.015 | 2,132 |
| final 2x32 | 256 | labels | 0.795 ± 0.012 | 0.917 ± 0.013 | 0.624 ± 0.028 | 0.543 ± 0.023 | 2,132 |
| final 2x32 | 256 | self-KD | 0.805 ± 0.010 | 0.937 ± 0.006 | 0.592 ± 0.022 | 0.512 ± 0.017 | 2,132 |
| final 2x32 | 512 | labels | 0.789 ± 0.000 | 0.935 ± 0.002 | 0.645 ± 0.003 | 0.563 ± 0.004 | 2,132 |
| final 2x32 | 512 | self-KD | 0.791 ± 0.002 | 0.940 ± 0.000 | 0.632 ± 0.002 | 0.550 ± 0.003 | 2,132 |
Reference points
- Bayes-optimal (the best any model can do on this problem)
- Predictions from the exact class probabilities, which the lab can compute because it generated the data. Test accuracy (20-way) 0.973, target-class AP ('bird') 0.999, test NLL 0.079.